OpenAI to Add Invisible Provenance Markers to ChatGPT Text in the EU
Over the coming weeks, text from ChatGPT and Codex will carry invisible signals for eligible users in the EU. The detector goes first to approved researchers, and editing or translating the text makes the signal much harder to find.
On October 5 (local time), OpenAI announced a plan to embed invisible provenance markers in text it generates. The move is intended to align with the EU AI Act. Over the coming weeks, the markers will roll out gradually to eligible users in the EU for text produced by ChatGPT and Codex. They apply regardless of subscription tier, but they will not be on by default for users worldwide at launch.
What mark does the text carry?
A technology called textGrain embeds invisible statistical signals in the process by which the AI chooses words. A dedicated detector then checks whether a piece of text carries OpenAI’s watermark signal. The marker is not visible to readers; instead, a separate tool is used to find the traces. OpenAI says it plans to open-source the technology.
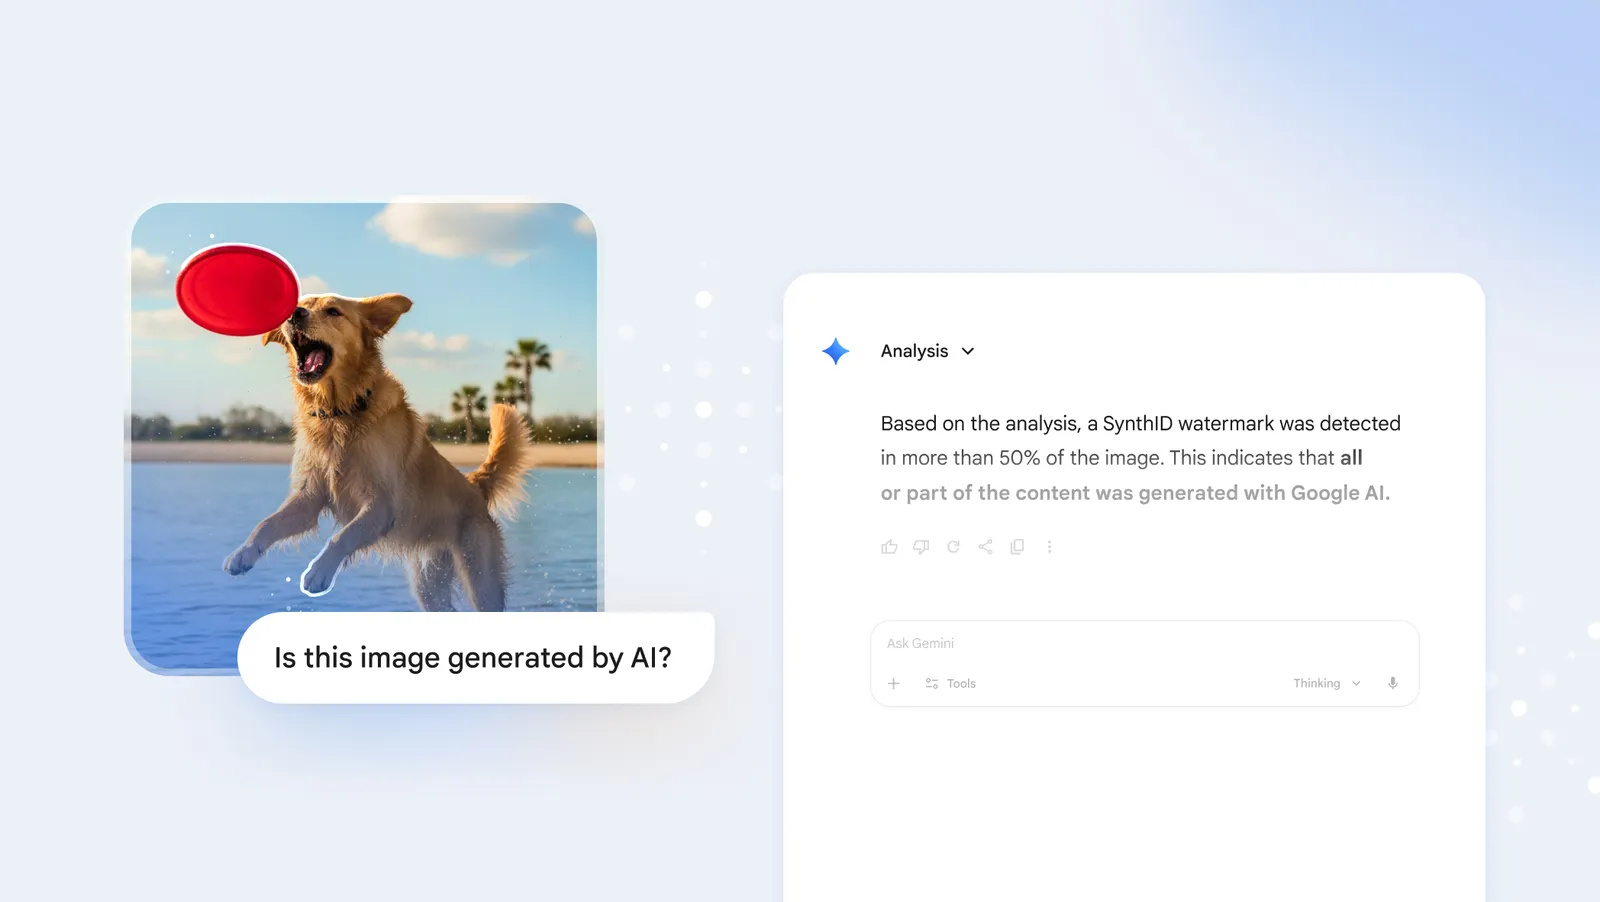
OpenAI already applies provenance markers to images and audio. Supported images carry Content Credentials, which hold provenance information, and supported images and audio carry an invisible SynthID watermark. The existing image and audio verification tools, along with provenance-checking features for developers, remain available.
Will small edits defeat detection?
Detection rates varied by the length and subject matter of the text. When the rate of falsely flagging unwatermarked text as watermarked was held at 1%, detection reached roughly 80 to 95% for text in the field of psychology. As text length grew from 200 tokens to 400 tokens, detection rates rose as well. In mathematics, by contrast, where there is less room to vary word choice, detection rates fell sharply.
Source: OpenAI
Tinkering with the wording pushed detection rates down further. In a 400-token passage, replacing 10% of the words with synonyms dropped detection from about 92% to 66%. When 25% of the words were swapped, it fell to 17%. OpenAI explained that short passages, text that has been edited or translated, and text written by unsupported models may also be difficult to detect.
OpenAI said the marker does not reveal how much a human contributed, the identity of the user, or whether the text is accurate. It also noted that the absence of a signal is no guarantee that a piece of text was written by a human.
Who can use it, and when
For developers integrating the feature into their own services, it became available as an option on October 5. Customers worldwide can configure certain models to return watermarked text, with the setting off by default. OpenAI said it is working with its cloud partners to extend the feature to its models offered through them within a few weeks. Starting the same day, researchers and expert organizations can apply for detector access, which OpenAI grants only to those it approves. Because of the risk of false positives and missed detections, OpenAI said it will not release the detector publicly at launch.
Image: OpenAI
OpenAI said adding the watermark did not degrade response performance. Running Astra through a range of performance evaluations showed no meaningful difference before and after the feature was applied. Individual benchmark scores went up in some cases and down in others.
In South Korea as well, developer customers can opt into watermarking on certain models. The questions worth watching from here are whether the signals can be reliably detected in Korean-language text, and whether they survive editing or translation. Errors that emerge during this initial use by researchers and expert organizations will be another variable shaping how widely the detector can actually be used.