From Logos to Explainer Videos: 10 New AI Tools
A look at ten projects released on GitHub over the past two months, from tools that lock in a specific visual style to ones that handle voice conversation and video production.
AI tools for working with images, audio, and video have been landing on GitHub in quick succession over the past two months. What they have in common is a narrow focus. Some lock in a particular visual style for logos or posters; others turn a bare topic into a finished explainer video. Several of the ten are “skills,” bundles of instructions that tell an AI how to carry out a task step by step, and the list also includes a speech model and a video research project.
ip-as-logo-skill: rounded character logos
This is a skill for making character logos that strip out fussy detail and lean on rounded outlines. Backgrounds are a single color and compositions stay simple. It suits anyone who wants to knock out draft brand mascots. It is not tied to one specific AI product, and works in any compatible environment. It has 5,497 GitHub stars (the star is how users mark interest in a project).
Image: GitHub s1dashu/ip-as-logo-skill (MIT)
mono-color-skill: posters with a restrained palette
Feed it a topic, a sentence, an object, or a photo, and it produces images for posters, booklets, packaging, and the like. By default it works from one core color plus a touch of accent color. Ask it to use a single color and it will go fully monochrome. It fits anyone after the look of print work with a tightly limited palette. It has 3,264 GitHub stars.
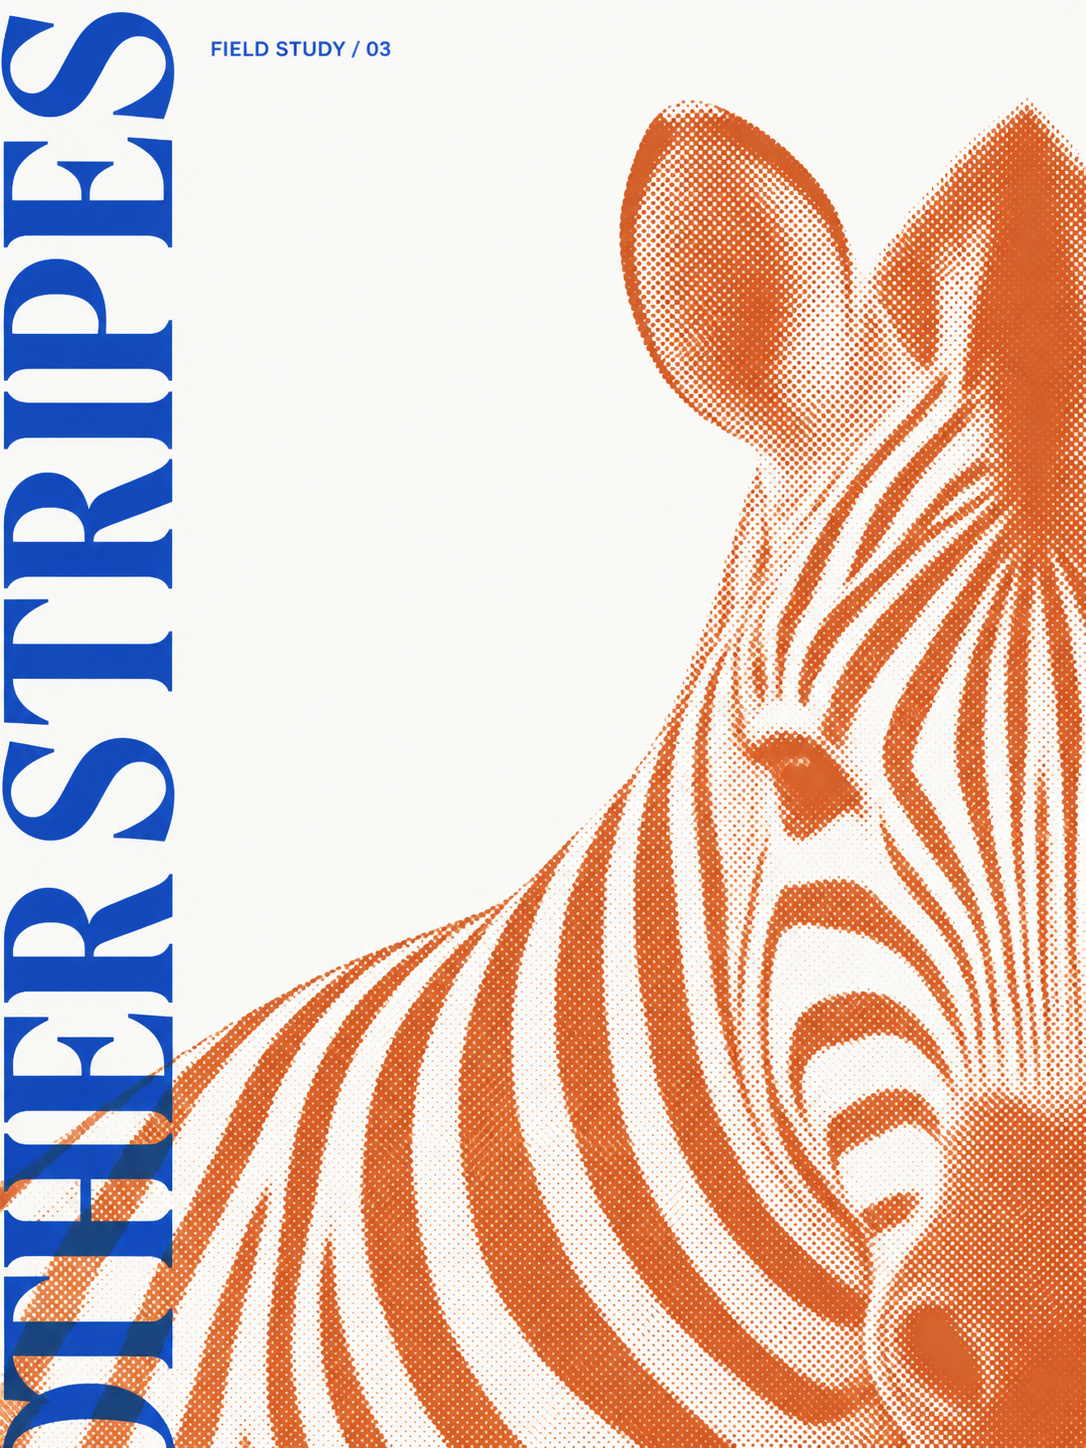
Image: GitHub yanliudesign/mono-color-skill README
qwen-audio-agent: keep talking while the agent works
This tool bolts real-time voice conversation onto an agent, an AI that carries out tasks on its own. The goal is to keep the conversation flowing even while the AI is running a search or using another tool. It is aimed at developers building AI services that communicate by voice. It has 2,759 GitHub stars.
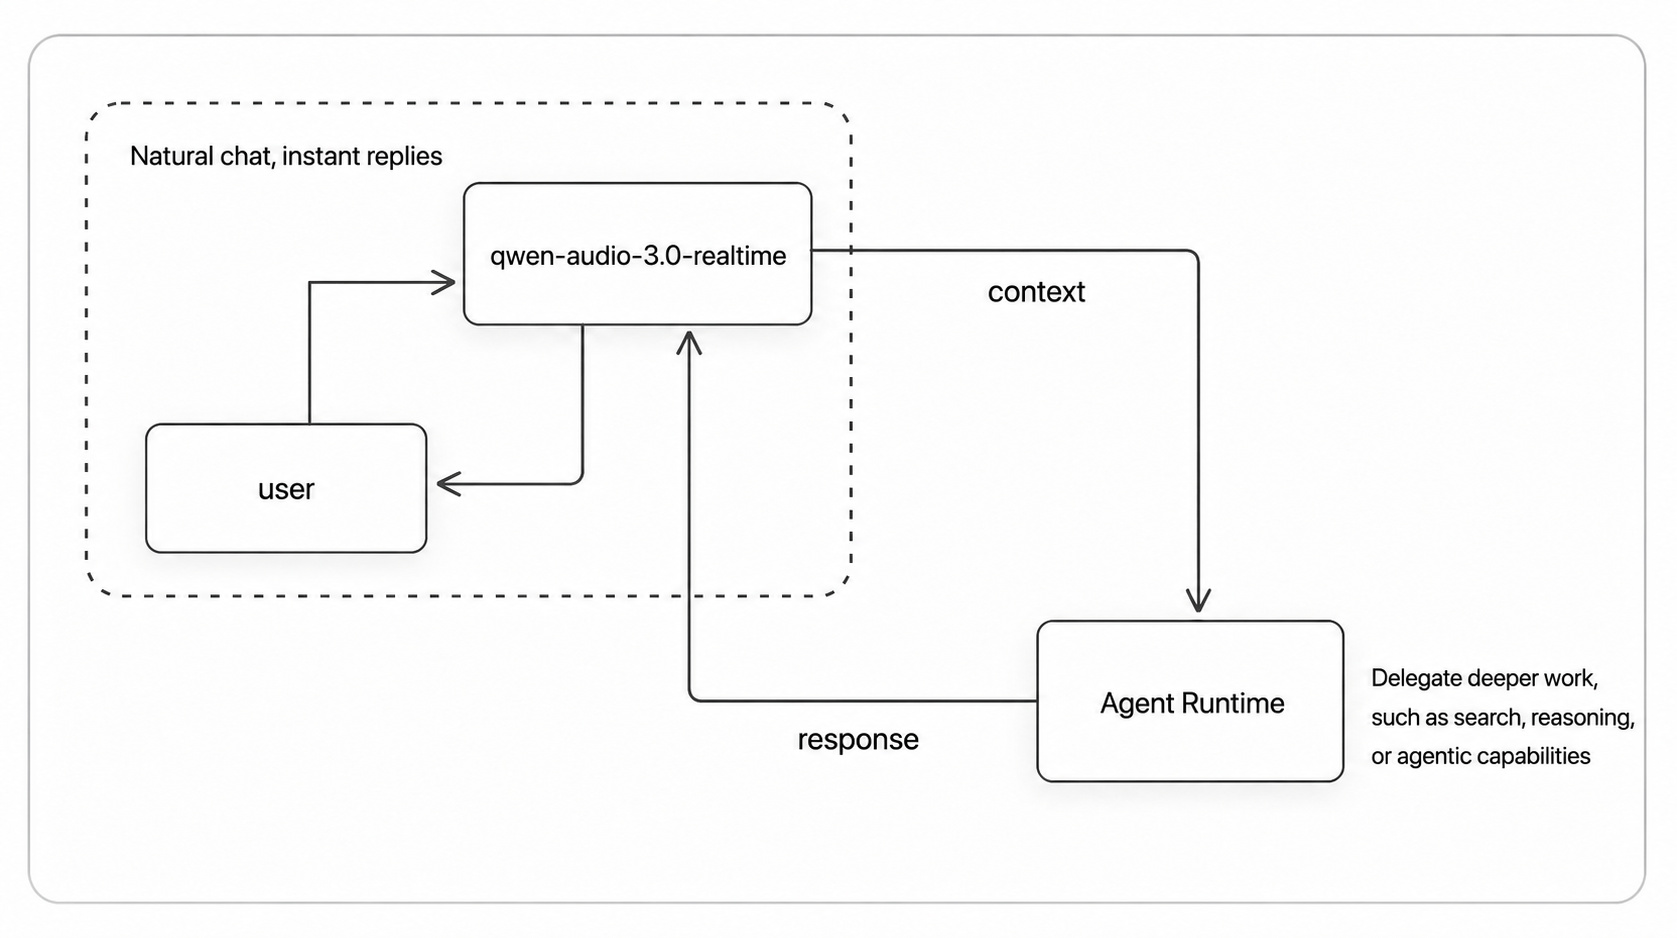
Image: GitHub QwenAudio/qwen-audio-agent README (Apache-2.0)
anything2explainer: turn a topic into an explainer video
A skill that takes a topic in Claude Code or Codex and builds an explainer video around it. Animated graphics run over a black background, with voice narration and subtitles on top. Instead of filmed footage, the visuals are drawn programmatically. It suits people producing explainer videos in Chinese and English. It has 2,041 GitHub stars. The license is PolyForm Noncommercial 1.0.0, which permits noncommercial use only. Using it to make money requires separate permission.
4DAnyone: see a person in a video from multiple angles
This converts footage of a person shot with a single camera into video from multiple viewpoints. It feeds into follow-up work that reconstructs moving figures in 3D. You do not need to lock the camera down during filming or supply camera parameters separately. It can export up to several dozen viewpoints. On September 16, a feature for inspecting and manipulating the results on screen was also released. It has 1,376 GitHub stars.
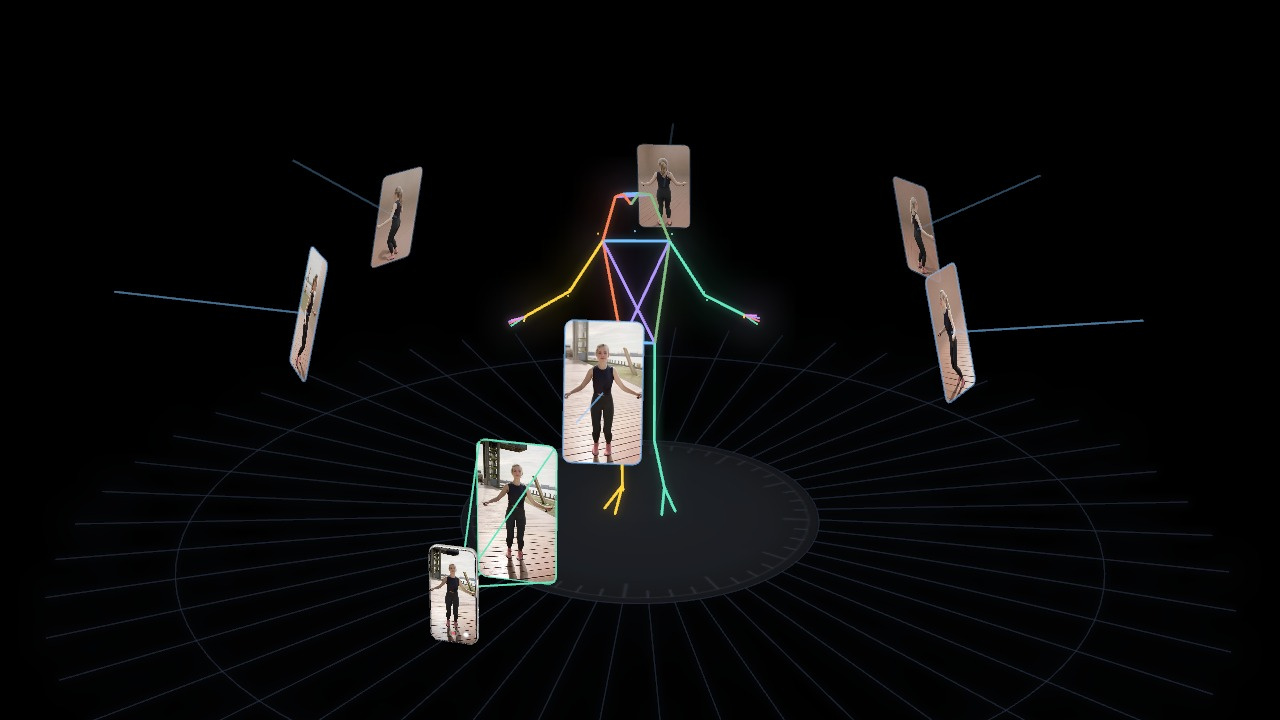
Image: GitHub ant-research/4DAnyone README (Apache-2.0)
AuK: generate and edit speech
A model for generating and editing speech. Worth a look for anyone who wants to run speech AI on their own machine. On September 13, support for running the model on computers with Apple’s own silicon was added. On September 16, the project said it had cut memory use in some of its audio processing components by roughly 7.5GiB. It has 1,252 GitHub stars. The license is the relatively permissive MIT license, applied to the training code, inference code, and model files that Tencent released.
lanshu-create-ai-presenter-video: make videos of a person speaking
A Codex skill that takes a topic or script plus a photo of a person and produces a presenter video. The photo must be of an adult and cleared for use. It bundles the whole production pipeline into one flow, from tidying the script through speech, lip sync, subtitles, editing, and quality checks. It is not locked to a single vendor and picks whichever tools are available in the runtime environment. It has 1,016 GitHub stars.
Image: GitHub cclank/lanshu-create-ai-presenter-video (MIT)
ComfyUI-H3-Motion-Context: stitch short clips together
This helps stitch together short clips made with MiniMax H3 inside ComfyUI, the image and video generation tool. It passes the final frame and audio of one clip into the generation of the next. The design intent is for motion and voice to carry over even as scenes change. It suits anyone making videos that chain several scenes together. It has 1,009 GitHub stars.
Image: GitHub NikoDemon80/ComfyUI-H3-Motion-Context (GPL-3.0)
travel-photo-abstraction: turn photos into pared-down graphics
A Codex skill that analyzes travel or everyday photos you supply. It extracts features such as shape, layout, proportion, and color. Those features are then translated into a small number of visual elements and redrawn as a spare graphic. It has 772 GitHub stars. The license is the “Travel Photo Abstraction Source-Available License 1.0.” Using it as received is allowed, but modifying the skill and documentation and redistributing them is restricted.
SolarWM: a research project on long-horizon video dynamics
A research project aiming at a model that handles how video changes over long stretches of time. It puts open data and training methods front and center. It leans more toward researchers studying how video models are trained than toward general users. It has 709 GitHub stars.
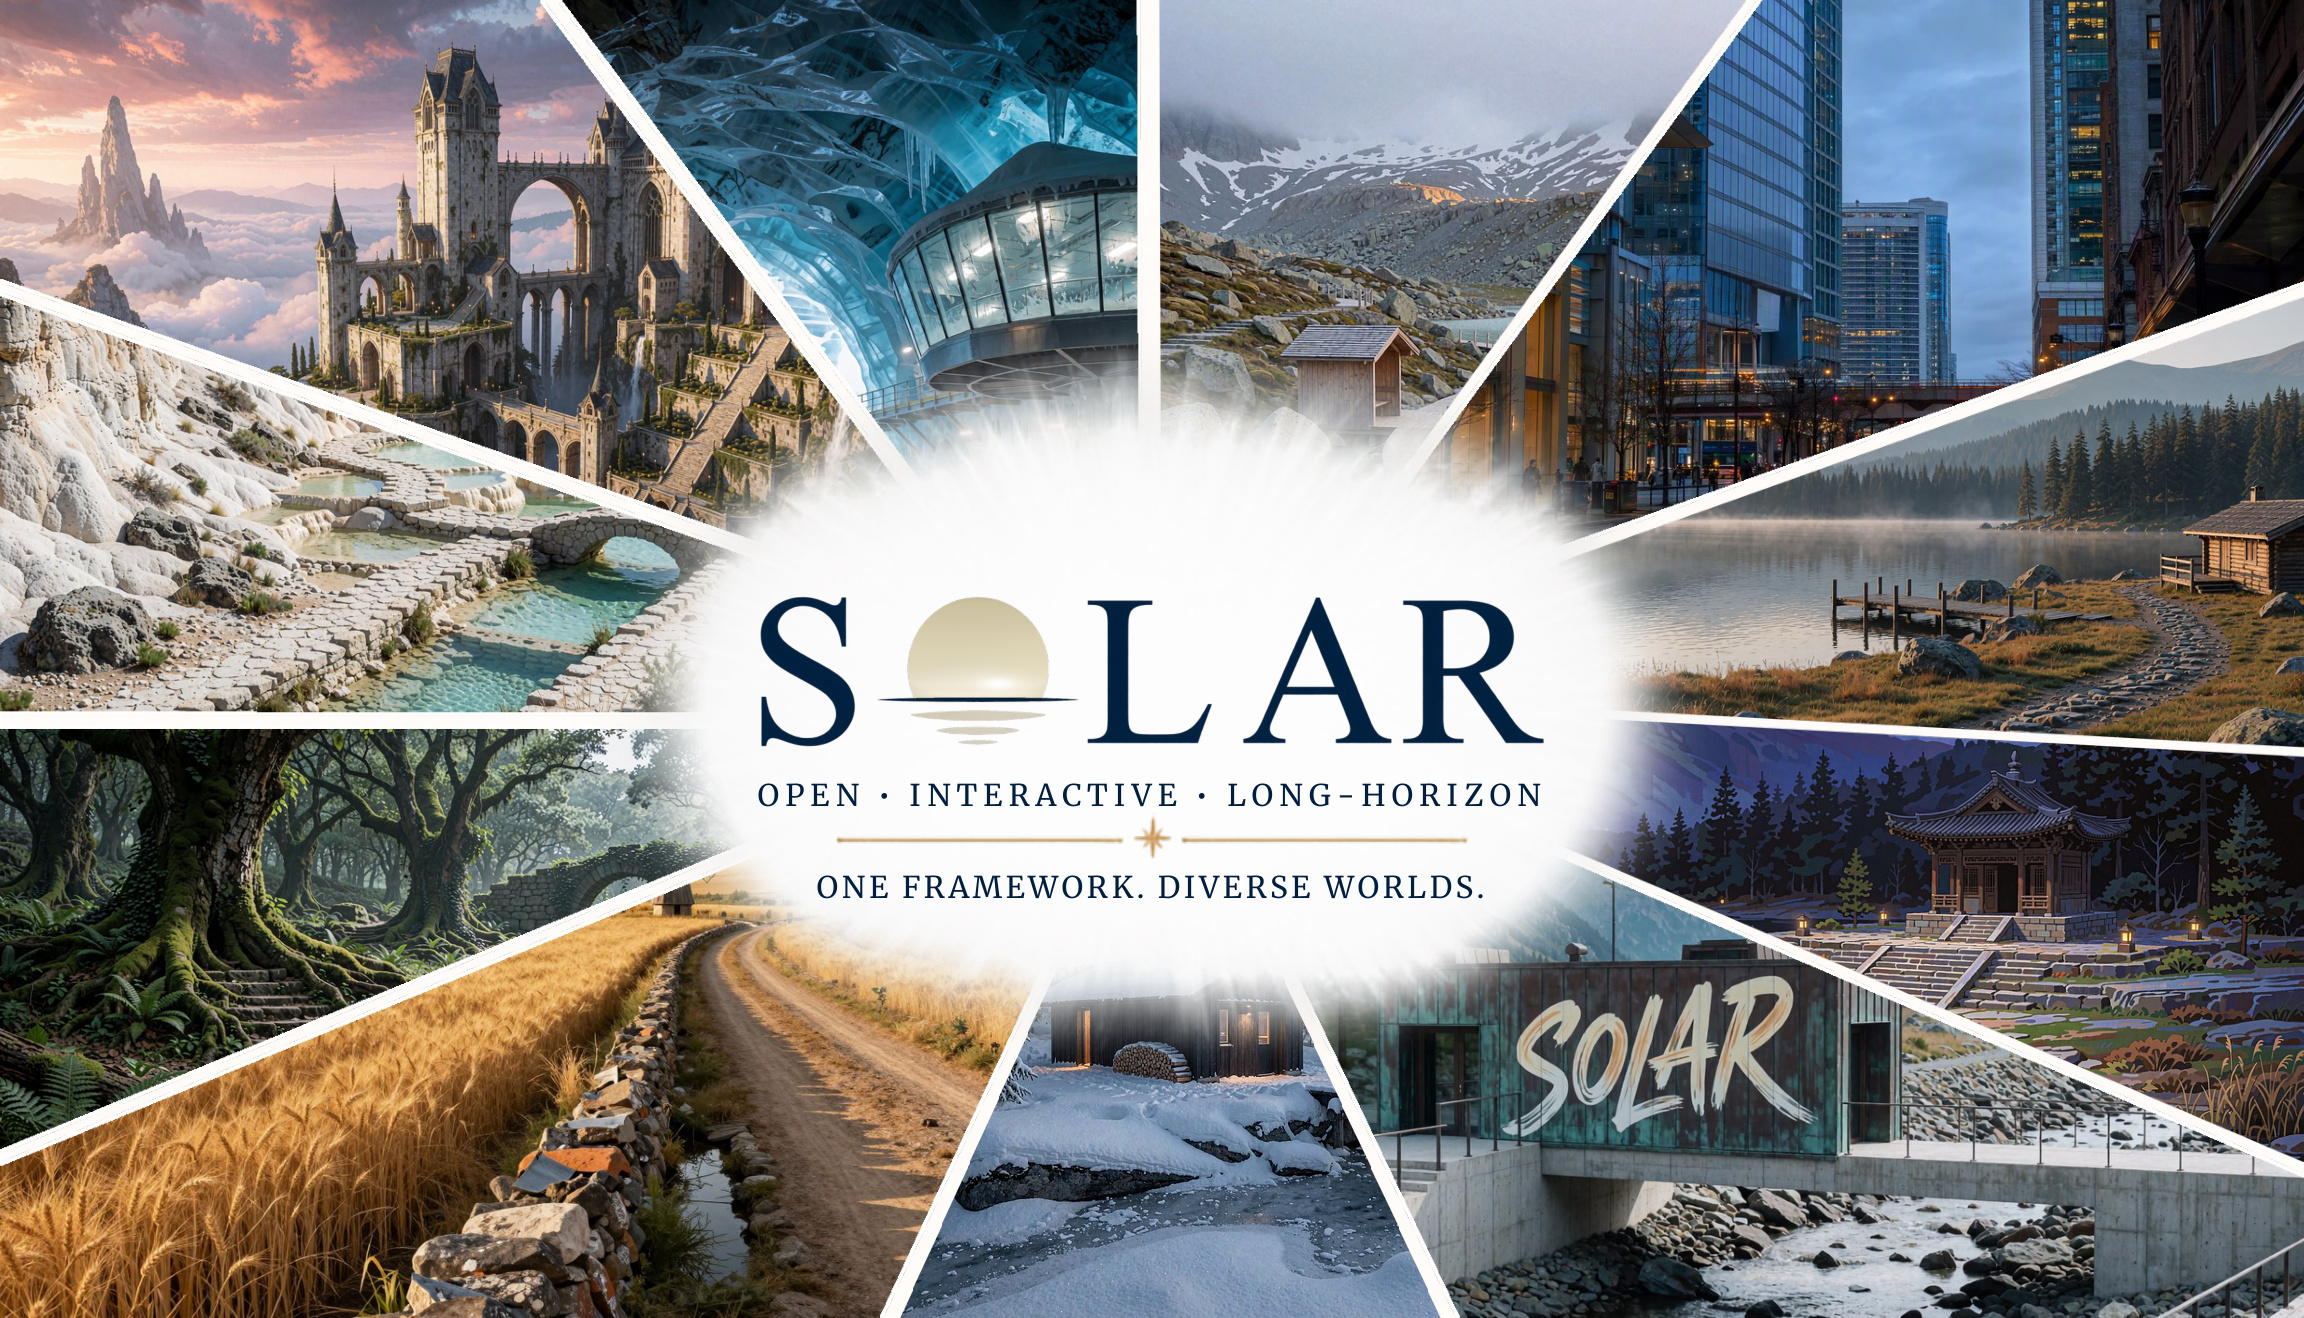
Image: GitHub Junchao-cs/SolarWM README (Apache-2.0)
Before you try them
The tools gathered here do not stop at generating pictures. They focus on fixing a visual style, editing audio, and chaining together the stages of video production. Star counts are only a rough gauge of how much attention a project has drawn. To judge whether something is actually usable, start by checking whether it produces the result you want. Korean language support and the cost of running it are worth weighing too. Licenses differ from project to project, so if you plan to use any of these commercially, read the terms first.
Sources
- s1dashu/ip-as-logo-skill: A compact Agent Skill for highly simplified, rounded, subtly neo-skeuomorphic IP mascot logos.
- yanliudesign/mono-color-skill: One-ink editorial print image skill — warm paper, halftone photography, active negative space, and restrained typography.
- QwenAudio/qwen-audio-agent: A realtime voice runtime that keeps Agents talking, working, and present. Real-time Voice Runtime for AI Agents